Use case · FinOps for coding agents
Your AI coding bill is growing. Can you explain what you got for it?
Finance can see the agent invoices. Engineering leads can see commits and pull requests. Neither can say what the spend actually produced. Cardinal follows agent spend from Claude Code, Codex, Cursor, and Gemini to the work it went into, and shows whether that work merged, is still moving, or was lost.
Same week, same team. One spend merged. One was lost.
On the invoice, both of these are just tokens. Cardinal follows each one to the initiative it served, the pull request it produced, and what happened to that PR.
Agent spend
$14.20
3 sessions · Claude Code
Initiative
feat/outcomes-observability
typed from the branch
Pull request
#421
reconciled from GitHub
Outcome
MERGED
head SHA matched the merge
Agent spend
$27.80
5 sessions · Claude Code
Initiative
feat/bulk-export
typed from the branch
Pull request
#418
reconciled from GitHub
Outcome
LOST
closed unmerged · superseded by #433
On our own team, 27% of one week's agent spend went to PRs that never merged.
Cloud FinOps exists because a $5M AWS bill isn't an answer; you need the team, service, and workload behind it. Agent spend is heading the same way. Cardinal splits attributed spend by what happened to the work, so the question stops being "how many tokens" and becomes "how much of this became software." Sessions that can't be tied to a branch are footnoted, not forced into a bucket.
$2,372 agent spend
Cardinal's own team · one week
- MERGED
$66728%
Became merged code.
The branch the session worked on produced a PR that merged.
- IN-FLIGHT
$55723%
Attached to work still moving.
The PR is open. The money isn't lost; it hasn't landed yet.
- AD-HOC
$50221%
Exploration, no PR expected.
Sessions on research/ or spike/ branches, or on main: investigation and scoping where no PR is expected.
- LOST
$64627%
Didn't merge.
The PR was closed unmerged, went stale, or was superseded. Some of it may have informed the work that replaced it.
Cost comes from each agent's own usage records, not estimates. Usage-billed and plan-billed sessions are reported separately, so a total never mixes the two.
Overview · the same week, in the product
Click to enlarge · esc to close
The questions your agent bill can't answer.
Is agent spend turning into delivered work?
Not tokens per engineer. The share of spend that ended up in merged code, and what each merged PR cost to produce. Every PR row carries its cost, the sessions behind it, the model that did the work, and its outcome.
Pull requests · cost and outcome per PR
Click to enlarge · esc to close
Where is the money leaking?
Lost spend is itemized, not averaged away: closed PRs, stale branches, and superseded work, each with its dollar figure. The spend curve flags days beyond +2σ, so a runaway week doesn't hide in the monthly total.
Sessions · outcome, model, and drift per session
Click to enlarge · esc to close
Which initiatives is the agent budget actually funding?
Sessions roll up into initiatives, and the backend PR and the UI PR for one feature collapse into a single line. Each initiative shows who worked on it, the PRs it produced, whether it shipped clean or is stuck, and what it cost. That's the unit a roadmap review actually talks about.
Initiatives · cost and delivery state per initiative
Click to enlarge · esc to close
Are you paying top-tier prices for routine work?
See which model tier the spend lands on, and compare $/Mtok across people doing the same kind of work. When similar work is landing on a cheaper tier elsewhere in the org, that's a candidate to move.
Model mix · spend by model tier
Click to enlarge · esc to close
The same ledger, cut by repo.
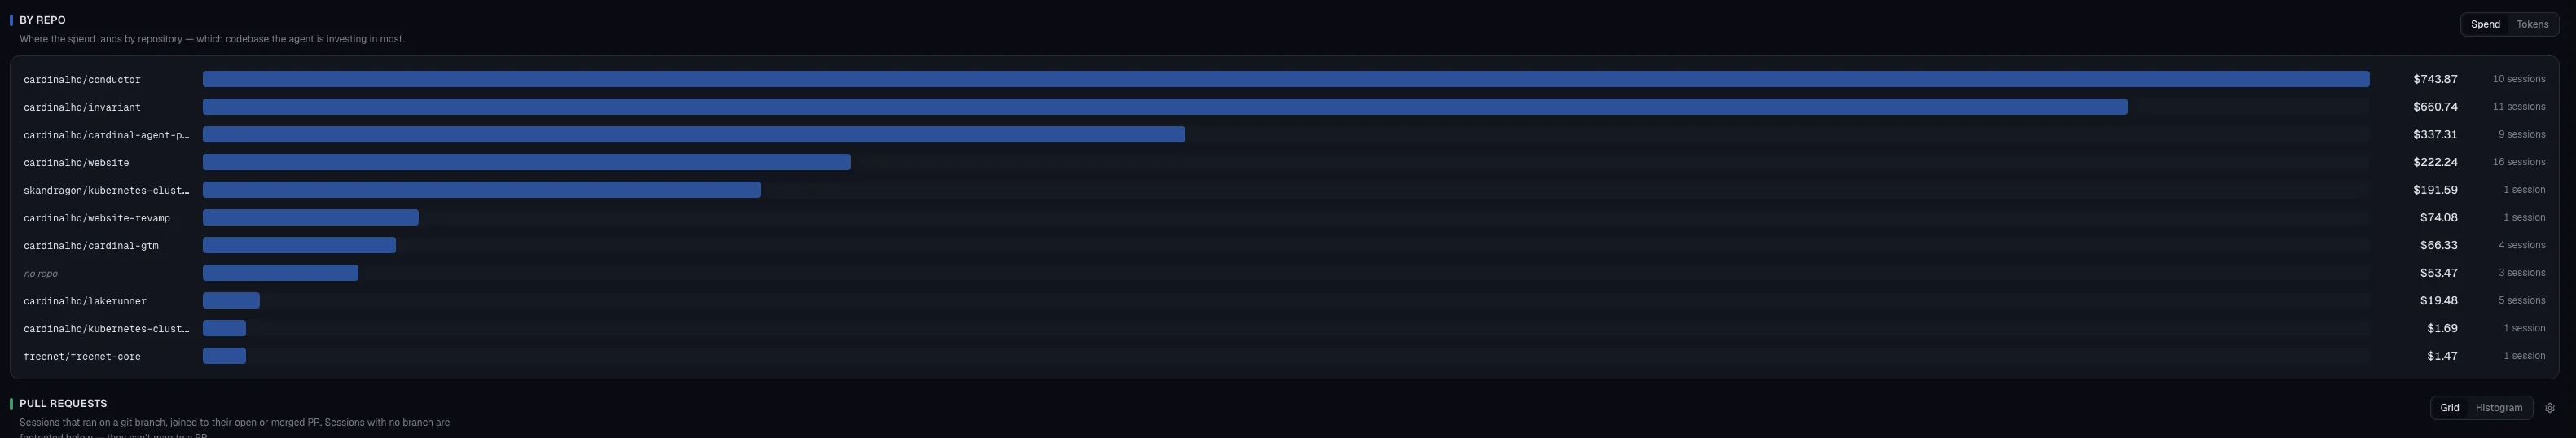
By repo
Which codebases the agent budget is going into, and whether that matches where your priorities are.
No productivity score. Nothing to take on faith.
Cardinal doesn't grade your engineers, and no model decides whether work was valuable. A finance partner and a staff engineer can open the same row and see the same evidence: the sessions, the branch, the PR, and the rule that classified it.
- Outcomes come from your systems of record.
- Merged, open, and closed are read from GitHub and joined to sessions by branch and head SHA. No model decides whether a PR was valuable.
- Uncertain matches stay visible.
- Attribution confidence is shown on every row and never silently rolled into the total.
- Unattributable spend is footnoted, not failed.
- Sessions with no branch can't map to a PR, so they're listed separately instead of being counted as LOST.
- Every number regenerates.
- Rows are reproducible from versioned rules, predicates, and attribution. A scorecard you cite in a quarterly review can be regenerated a quarter later from the same trace.
How it works
Your coding agent doesn't know whether the work mattered. Your systems of record do.
Cardinal observes what the agent did and joins it against where delivery is recorded. Here's the machinery, for the engineer you'll forward this to.
Where work happens
- Claude Code
- Codex CLI
- Cursor
- Gemini CLI
Cardinal
Deterministic- Tokens
- Sessions
- Initiatives
- Outcomes
Joins what the agent did to where the work was recorded.
Where outcomes are recorded
- GitHub (Pull requests, available)
- GitLab (Merge requests, coming soon)
- Jira (Issues, coming soon)
- Linear (Issues, coming soon)
Today: GitHub PR lifecycle state, joined by branch and head SHA.
Using something else? Tell us.
Every session is a row
A small plugin in each engineer's agent streams OpenTelemetry to Cardinal after every tool call. A local git hook adds the branch and head SHA, so each session knows which piece of work it belongs to.
- · git_state event fires post-tool, so nothing blocks the user
- · Cost priced from the emitter's own usage records, not estimates
- · Model, effort tier, skill, and drift are attributes on the row
Branches become initiatives
Cardinal parses the branch name (feat/, fix/, refactor/, infra/, research/, spike/) to name and type the initiative. Sibling PRs from linked branches collapse into the same initiative.
- · Convention: <type>/<kebab-name>, parsed on ingest
- · Engineers, tokens, cost, session count attributed per initiative
- · Spec conformance shown where a spec is attached
PRs carry the delivery signal
A PR reconciler polls your connected GitHub integration for lifecycle state on every branch Cardinal is watching, then joins by branch and head SHA.
- · GitHub App or PAT. One integration per org
- · Reconciler runs every 30 min; webhook lands sub-minute (opt-in)
- · Stuck / abandoned / on-scope pills come from PR state and spec joins
One ledger, every cut
The same session-level facts drive every view: by bucket, type, model, repo, and initiative. Nothing is re-aggregated in the UI.
- · By-type strip: Feature, Bugfix, Refactor, Infra, Research
- · Spend curve flags buckets beyond +2σ
See what your agent spend produced.
Walk through the ledger with us, or install the plugin and get your own the next day. One command, no code changes. Outcomes show up as soon as sessions close; PR attribution starts once GitHub is connected. Initiatives come from typed branch names (feat/…, fix/…), and common aliases are recognized.